“We should self-host the model” can sound like a complete privacy strategy. It is only a deployment choice—and it can bring a new set of responsibilities for data handling, access, uptime, upgrades, and hardware capacity.
Choose the model of operation after identifying the constraint you need to solve.
Start with the data and the workflow
List the information the feature uses, where it is stored, who can access it, and whether it needs to leave your environment. Consider whether you can reduce or redact sensitive fields before sending a request, or use a provider with contractual and technical controls that meet your requirements.
Then define the product's quality bar: response time, accuracy, availability, and expected usage. A local model that cannot complete the task reliably may not satisfy the user, even if it keeps inference nearby.
Compare the full operating cost
Hosted APIs can reduce infrastructure work and make it easier to use larger models, but costs and provider dependencies need monitoring. Self-managed inference can offer more control, but someone must handle deployment, scaling, observability, security updates, capacity planning, and incident response.
For either option, track usage, latency, failures, and quality. Add limits and graceful fallbacks so a burst in demand or an unavailable dependency does not turn into an open-ended bill or a broken feature.
Keep the architecture reversible
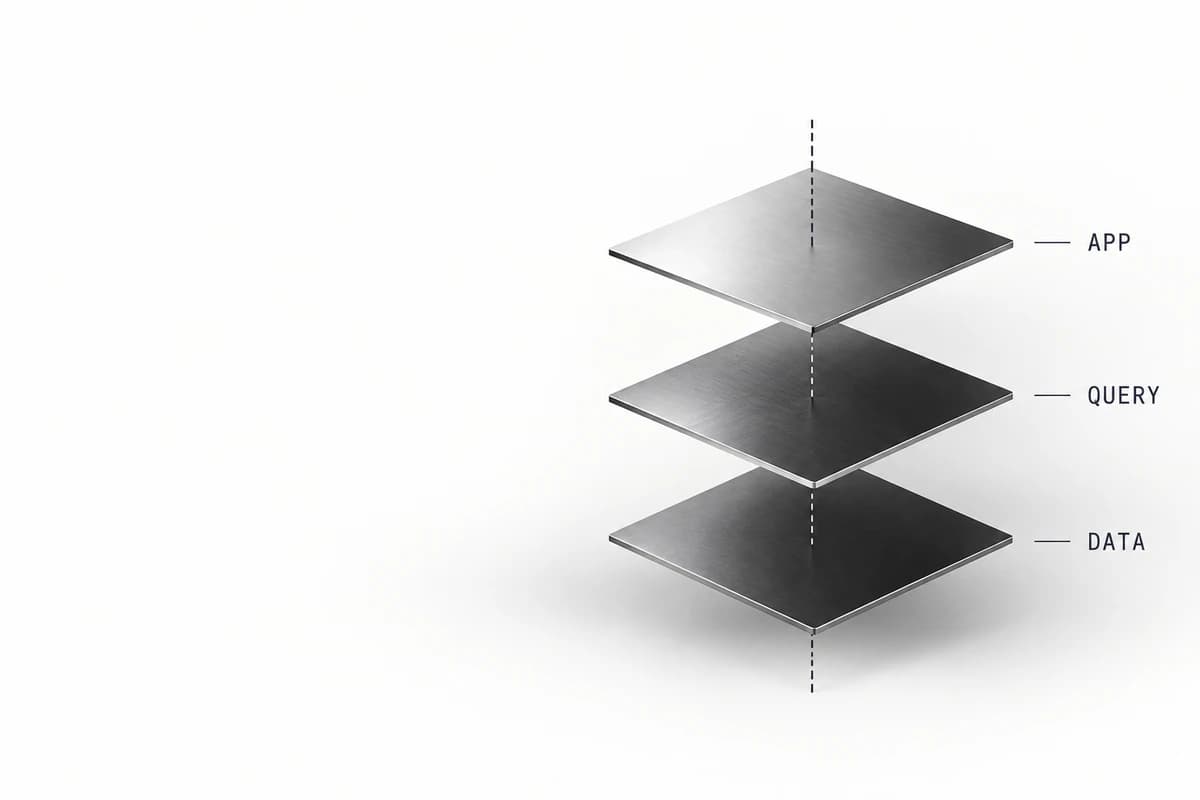
Put a stable application boundary around model calls. Keep provider-specific behavior in one place, define what the rest of the product expects, and test a representative workload before switching. Avoid building abstractions for hypothetical providers; make the parts likely to change replaceable.
Privacy is a system property, not a checkbox on a server. The right deployment is the one that meets the real data and user requirements while the team can operate it reliably. Sometimes that is a hosted service with careful controls. Sometimes it is self-managed infrastructure. Decide with evidence, not a slogan.